agent-ready-scanner
Free for noncommercial use under PolyForm Noncommercial 1.0.0; commercial use needs a licence from Rico. View the source
It answers one question per site, from raw HTTP only: can an AI agent read, understand, and act on this business's website? No JavaScript is executed, so the scanner sees exactly what an AI crawler or agent sees. Each site gets a 0-100 score, an A-F grade, and a per-category breakdown, written to results.json and a self-contained branded report.html.
The problem
More customers now reach a business through an AI assistant instead of a search results page. An assistant can only recommend, quote or book what it can read. Most small-business sites were built for people with a browser, and the person who maintains the site has no quick way to find out what an AI agent cannot see there. This tool hands that person a specific, ordered list of what is missing, so they can act on it. It does not touch the site.
How it works
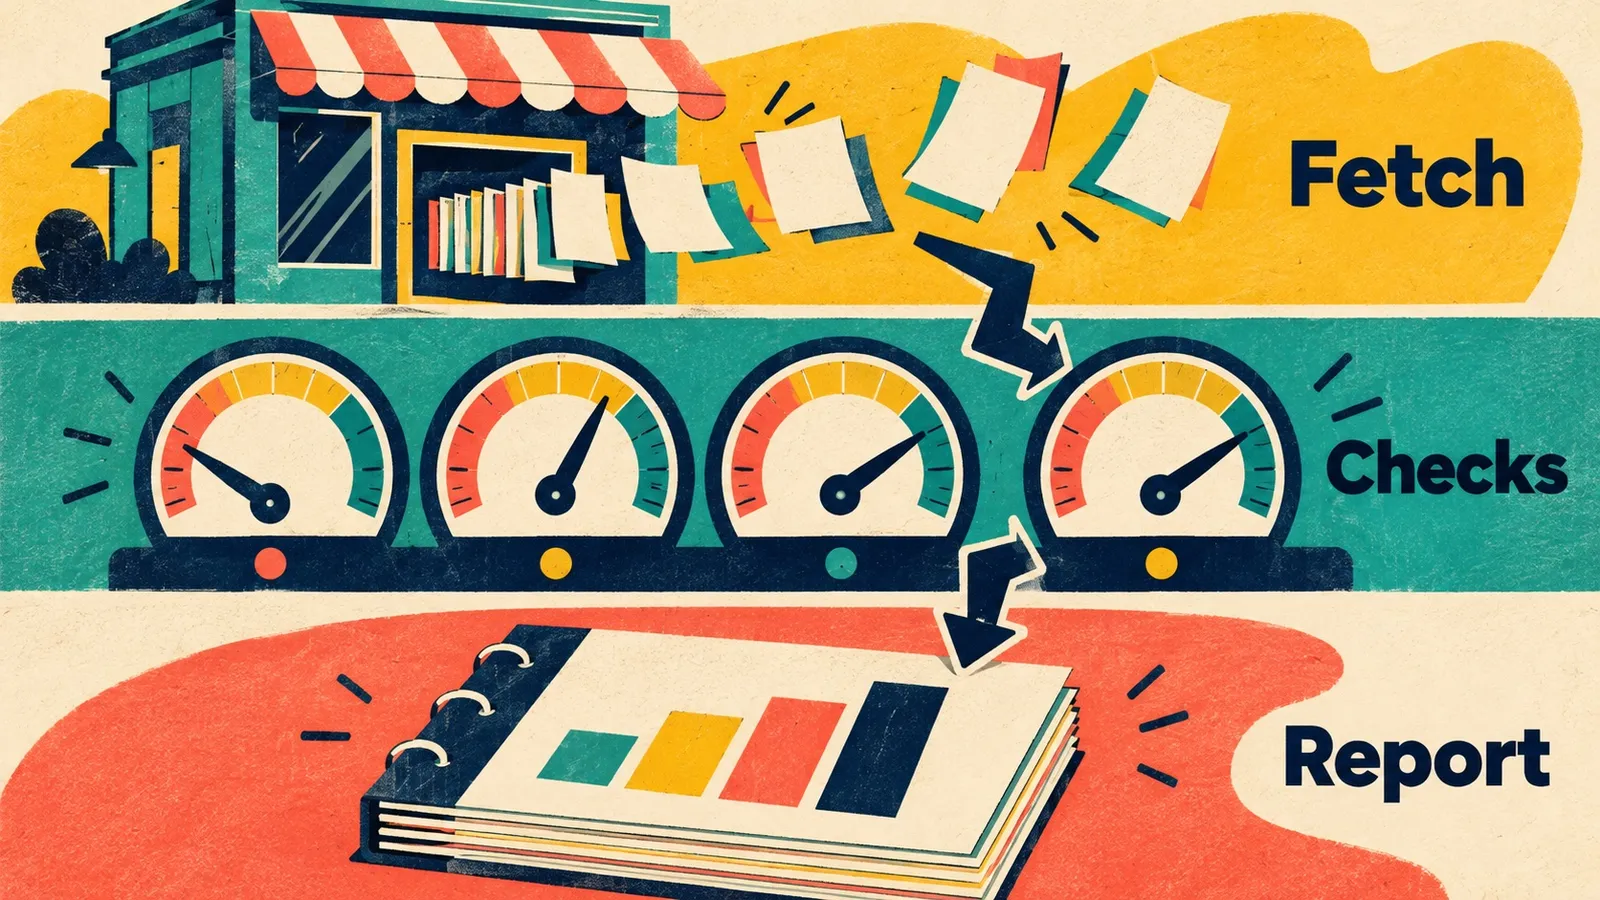
The CLI takes one --url or a CSV of vertical,name,url rows. For each site, services/fetch.py does the raw HTTP work (page fetch, visible text, JSON-LD extraction, robots.txt AI-crawler policy) through one httpx client. services/checks.py collects signals from the page and its side files (robots.txt, sitemap, llms.txt, /.well-known/ probes) and scores them with a fixed weight table. services/report.py renders the batch, grouped by vertical, into JSON and one offline HTML report. Results are Pydantic models (models/site_result.py).
Features
- Grades: A >= 85, B >= 70, C >= 55, D >= 40, F < 40
- Emerging signals are recorded but not scored: /.well-known/mcp.json, /.well-known/ai-plugin.json, HTTP 402 responses
- It never scores a site it could not read
How it was built
The first version was written in one day on 2026-08-17 to answer what an AI assistant can actually see on a small business's website. It was a uv Python app with a fixed seven-category weight table.
Two decisions date from that first commit: raw HTTP only, because AI crawlers do not run JavaScript, and deterministic scoring, so the same site always earns the same explainable score.
The first batch scanned 35 small-business sites on Long Island and averaged 66 out of 100. rTech's own site scored 79, then 94 after the missing files and booking link were added.
The code was written with Claude-based agents and then reviewed by a different model family. That review found a site blocking every crawler was scored as open, and that empty price data counted as a visible price; both were fixed.
Rico chose the second-family review on purpose, because a reviewer on the same model tends to miss what the author missed. Tests were proven red before they were trusted.