For teams that write their own copy: 5 to 15 researched customer composites each react to a draft alone; scripts check the run.
Active, version 1.2.3 (see CHANGELOG.md).
Rico Rojas, Fractional Forward Deployed Engineer. AI systems built inside your team: consulting for small and mid-size businesses, embedded engineering for larger ones. · [email protected] · GitHub

I am a fractional forward deployed engineer: an AI consultant for small and mid-size businesses, and an embedded engineer for larger companies. I go where the work happens, sit with the people doing it, and build AI agent systems inside real teams: agents, MCP servers, memory, review and evals, shipped with the logs on. The people stay in charge, and they get more done.
Sit with the people doing it, write down how the work runs today and where it gets stuck.
Ship the smallest version that does the job, with the deterministic parts in code and the AI only where code cannot decide.
A second model family reviews every change, and tests prove the behaviour, not the coverage.
Every run is logged and observable, and a person stays in charge of the decisions that matter.
For teams that write their own copy: 5 to 15 researched customer composites each react to a draft alone; scripts check the run.
Active, version 1.2.3 (see CHANGELOG.md).
For small-business inboxes: files mail into the owner's folders and drafts replies; it has no send tool, so the owner sends every message.
Active, beta.
For people running several AI agents: shared memory over MCP with role-scoped access; nothing is kept until a person or a set rule approves it.
Active, single-operator deployment.
For small trades: a plain-words job becomes a numbered, branded quote; a script checks the money math, and the owner reviews and sends it.
Experimental.
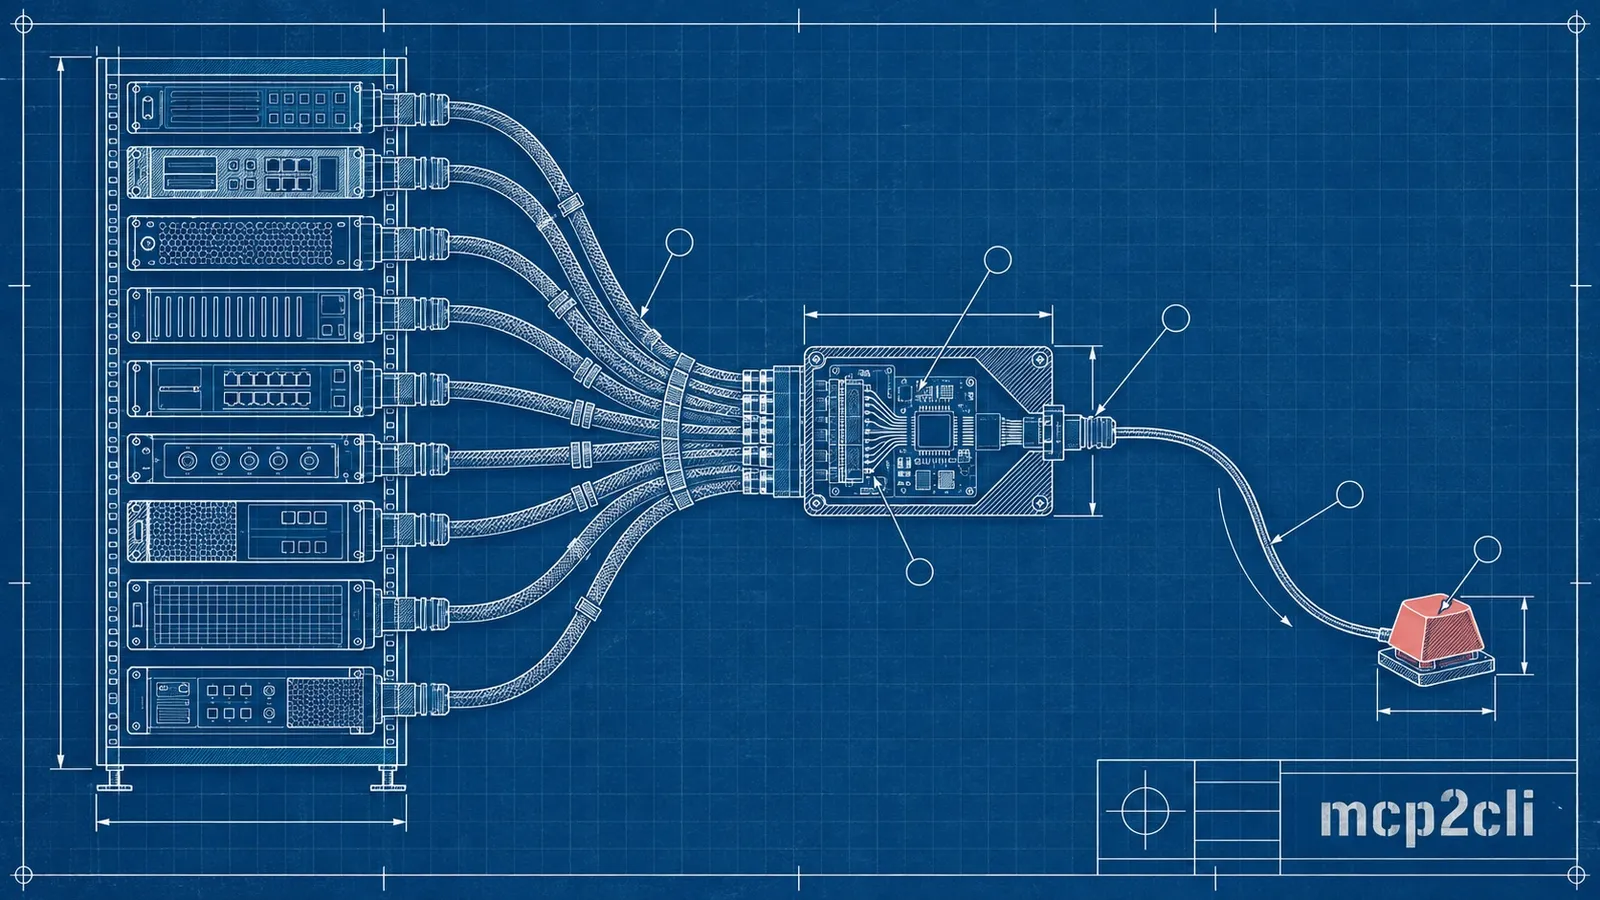
For agent setups with many MCP servers: each tool becomes a bash command, schema loaded on demand; JSON output, tested against a mock server.
Active.
For small offices: a document the firm already trusts becomes a checked template; nothing is released until the owner reads it and clicks accept.
Experimental, version 1.0.5.
For a small team of AI agents: tested code, not chat, decides who works next; people watch in chat and can pause or re-budget any task.
Experimental.
For small-business site owners: a 0-100 score and a list of what an AI agent cannot read on the site; it reads raw HTTP and never changes the site.
Active, version 0.1.0.
For owners and their coaches: a one-page audit of what the owner keeps and what their team can own; a fixed table, not the AI, grades each task.
Experimental, version 0.2.2.
For designers redoing a site: up to five AI design directions side by side, each traced to its references and brief; the site is never modified.
Experimental, single-user, run locally.
A small Python tool that turns an agent's reply into one spoken in-character line in a voice cloned from a 3 to 10 second clip.
Finished and small on purpose: version 0.1.0, 22 tests, CI green on Linux and macOS.
Pi Harness takes a diff (staged changes, a branch, or any git diff command) or a set of whole files, and sends it to specialised reviewer personas on…
Working tool at v2.0.
The owner photographs a pile of receipts and drops the photos in an inbox folder.
Experimental.
The owner drops in the text of a meeting (a transcript, or a voice memo already turned into text) and gets back, the same way every time:
Experimental.
A TypeScript/Bun library plus a small set of services that put a secret-manager control plane in front of a self-hosted Vaultwarden instance.
Active.
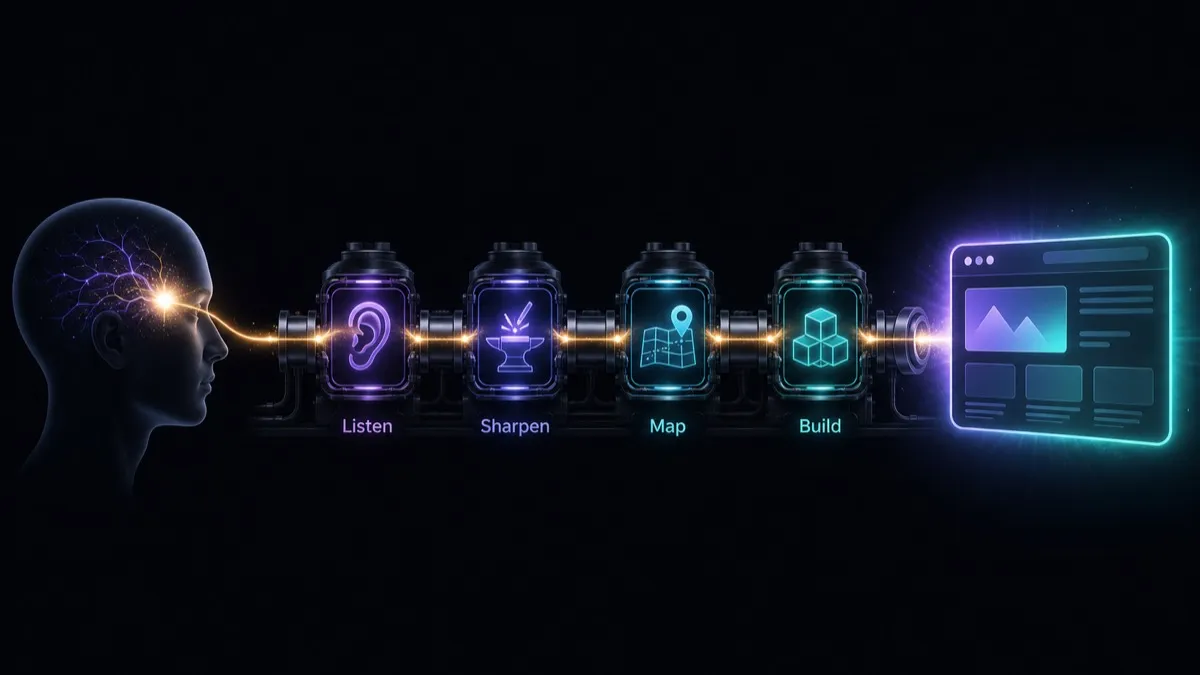
Idea Forge is a four-stage pipeline that runs inside whatever AI assistant the user already has.
Active, version 2.0.1.
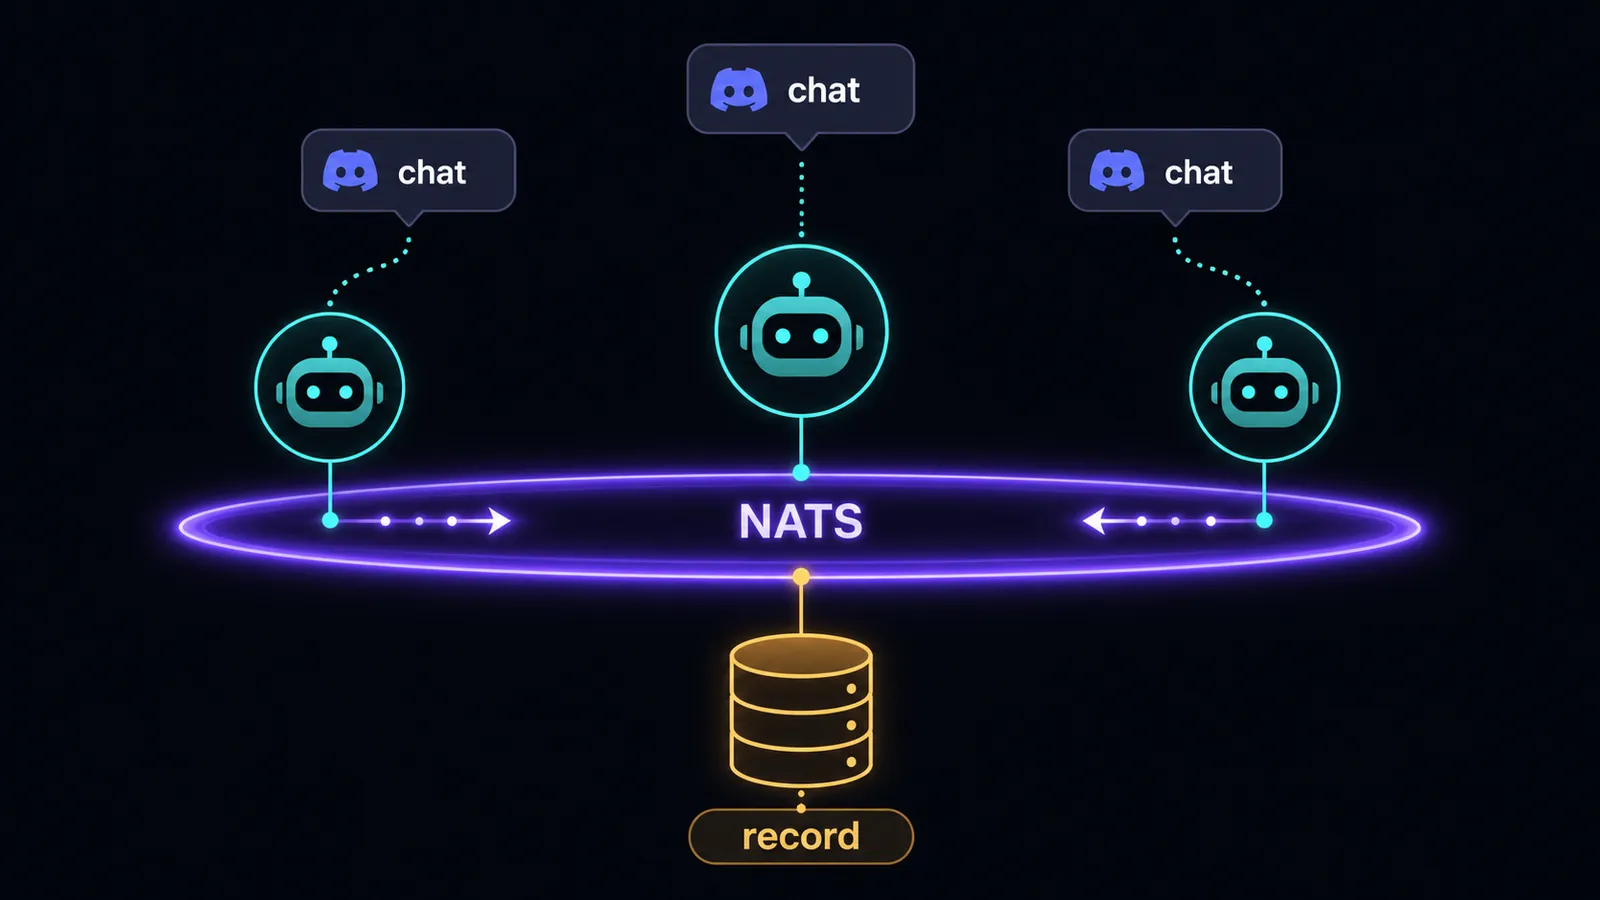
A runtime for long-running, steerable AI agents, each a managed Claude or Codex session supervised by its own daemon and coordinated over NATS.
Experimental.
A set of twelve Claude Code hooks that turn an operator's standing rulings into refusals, rewrites and loaded text, each with its own tests.
Active.
It installs a small memory folder the AI reads at the start of every chat and writes to at the end.
Active, version 1.0.4.
An orchestration service that reviews pull requests, triages issues and dispatches fixed jobs to disposable runner boxes for a set of private git…
Experimental export of a private system.
A small self-hosted server for a dictation app that issues device keys, relays speech and chat requests, syncs notes between devices, and serves a…
Experimental, version 0.1.0.
The owner pastes email threads (one, or a month of backlog).
Active, version 1.0.4.
Converts directories of audio into chaptered M4B audiobooks, enriches metadata from the Audible catalogue, and files finished books in a library.
Active.
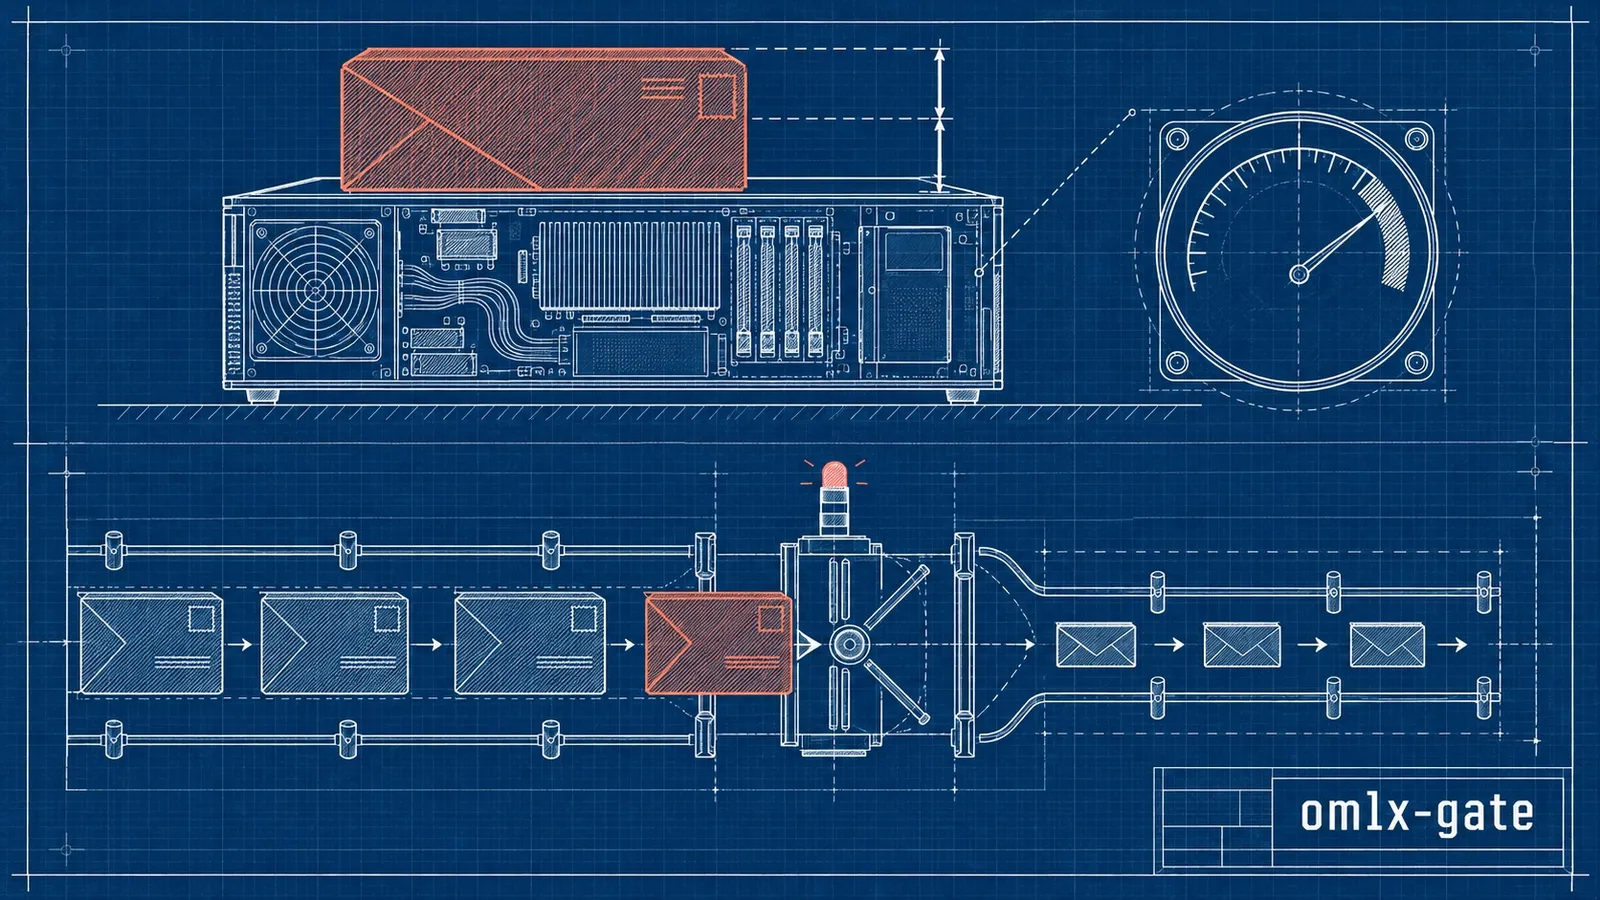
omlx-gate sits in front of oMLX's OpenAI- and Anthropic-compatible generation endpoints and decides, per request, whether a large model may run now.
v0.1.0.
Runs a set of JSON test cases against every model exposed by an OpenAI-compatible LiteLLM proxy.
Experimental personal tool, run locally.
This folder defines what an installable AI kit is and enforces it:
Experimental.
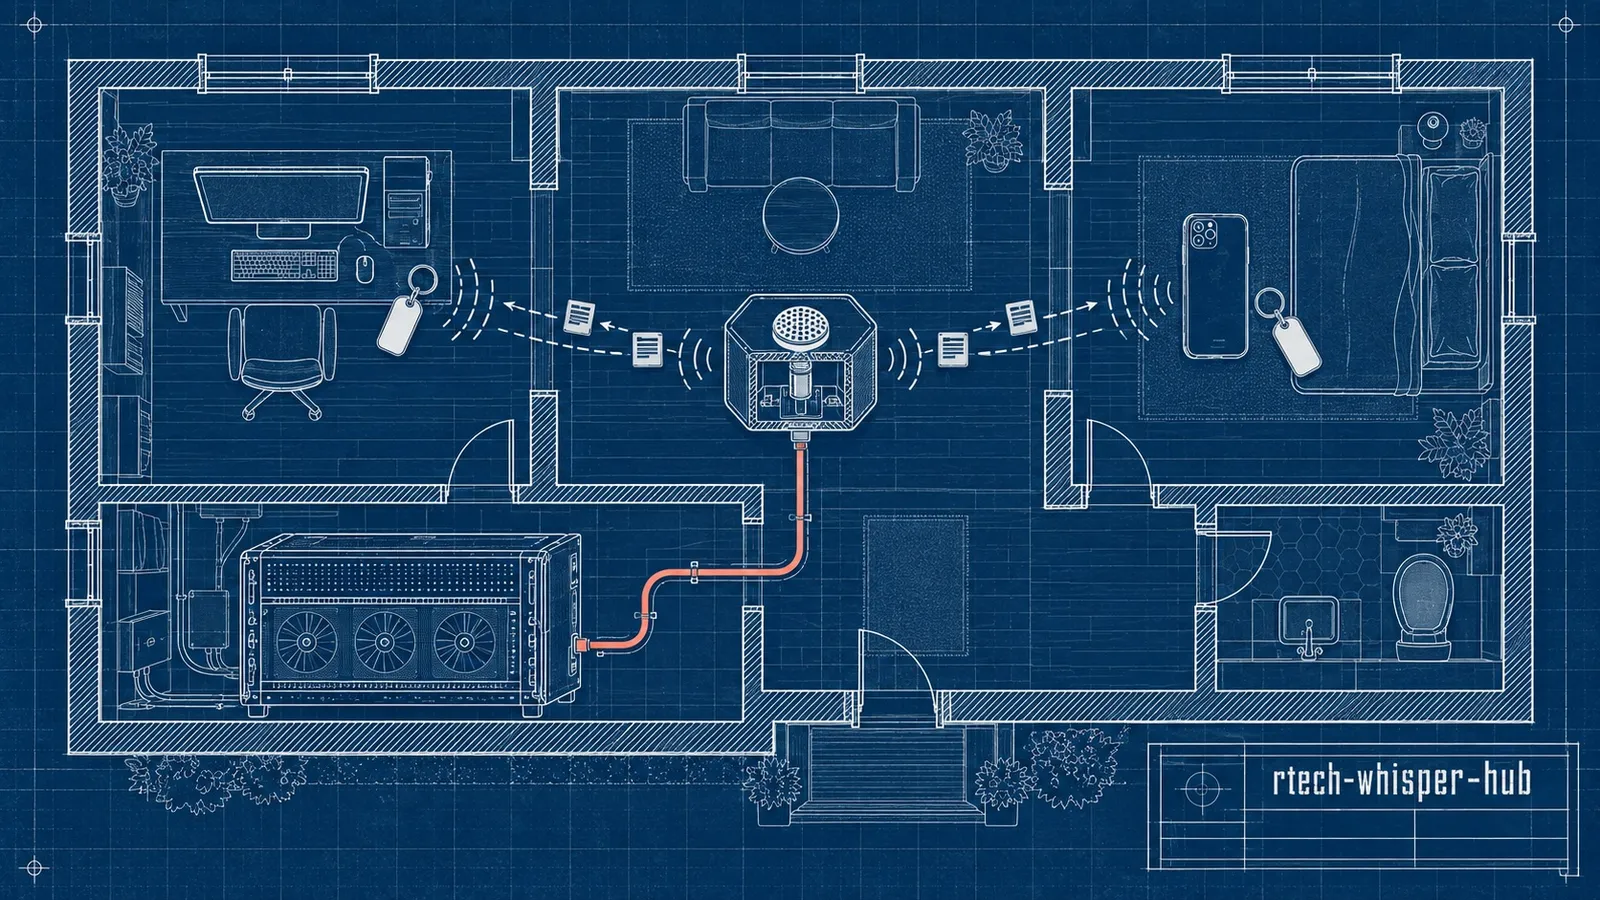
A native SwiftUI dictation app for iPhone that gets text back from your own Whisper server.
Experimental, version 0.1.0.
OBSERVABILITY_CONTRACT.md is the normative, semver'd spec for every log line an rTech service emits: fields, levels, labels, redaction, config and…
Contract 1.0.0 and the Python package (1.0.0) pass the fixture.
A TypeScript npm workspace holding a GoHighLevel (GHL) API client and a read-only MCP server on top of it.
Experimental, version 0.1.0.
The agency's letter goes in.
Experimental, version 0.2.3.
A macOS menu bar app that controls which SSH hosts AI coding assistants may connect to.
Experimental.