omlx-gate
Free for noncommercial use under PolyForm Noncommercial 1.0.0; commercial use needs a licence from Rico. View the source
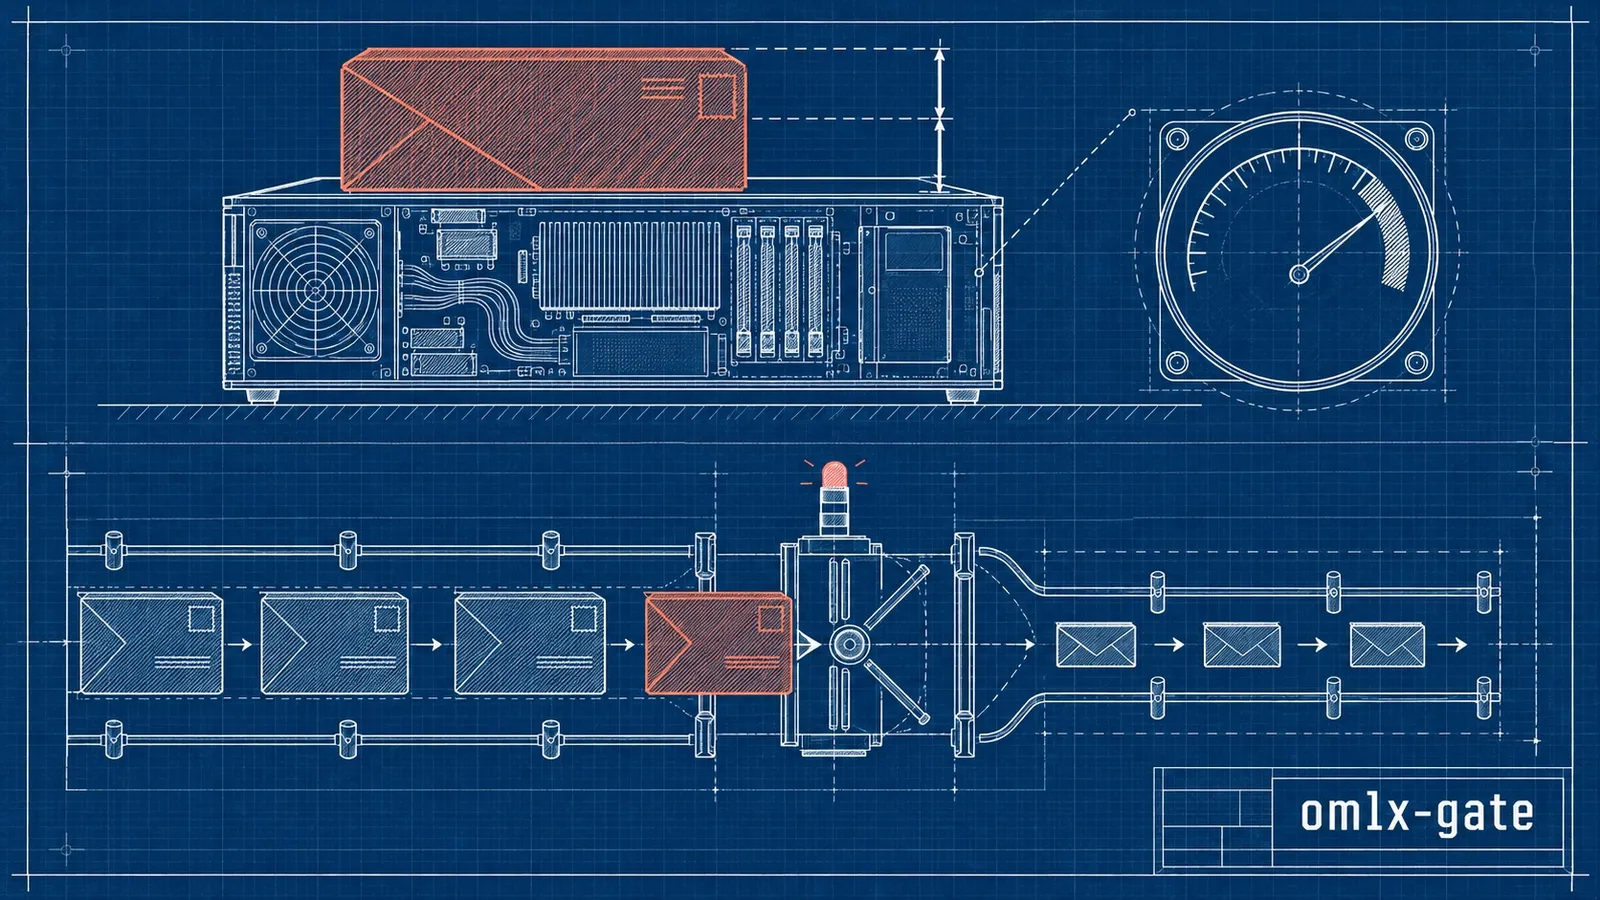
omlx-gate sits in front of oMLX's OpenAI- and Anthropic-compatible generation endpoints and decides, per request, whether a large model may run now. Small models (4B parameters or fewer by default, read from the model name) pass untouched. Larger ones get a global concurrency cap, a per-client rate limit derived from measured service time, a memory fit check before a model swap, and a cap on model loads per minute. Every gated response carries rate-limit headers and a suggested pacing interval, and GET /usage returns the whole live contract (limits, measured timings, loaded models, memory headroom) as one JSON document.
The problem
A single Mac with unified memory can hold one or two large models at a time. Several clients on the network sending requests to big models at once either queue behind each other until requests time out, or force model swaps that each take several seconds and can run the machine out of memory. oMLX's own memory guard refuses such requests with low-level error text that tells a client nothing about what to do next. The gate keeps the box responsive for everyone and tells each client exactly how to pace itself.
How it works
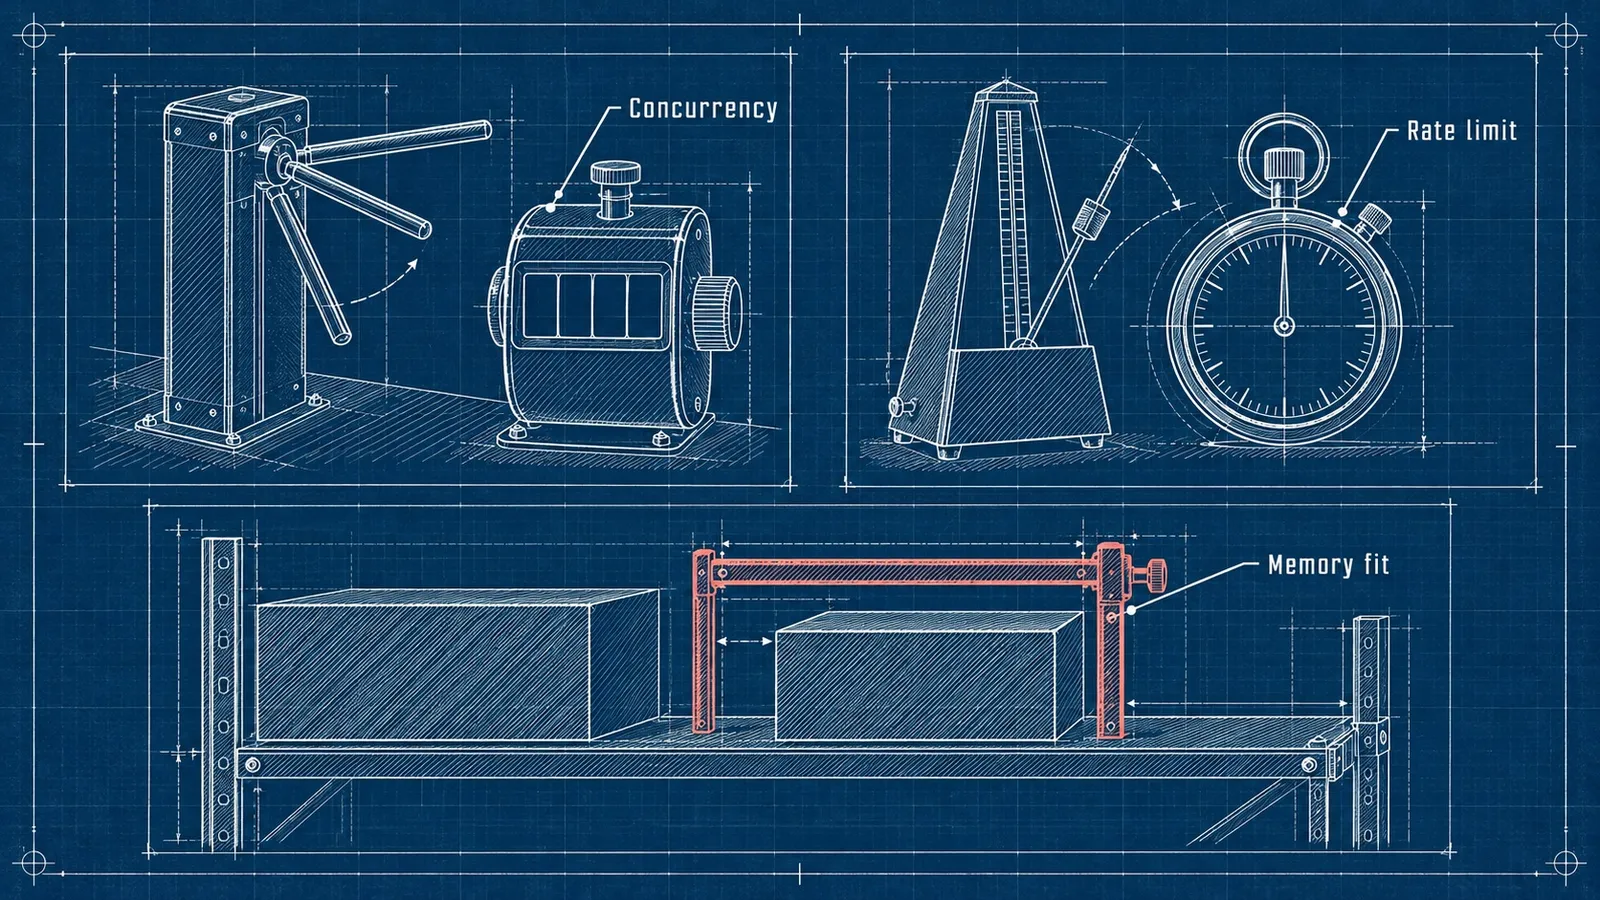
BigModelGateMiddleware is a pure ASGI middleware (no BaseHTTPMiddleware, so streaming responses pass through without an extra pipe layer). For a request to a gated path it reads the body once, extracts the model id, and runs three checks in order: concurrency (at most OMLX_GATE_BIG_CONCURRENCY big requests in flight, else 429), rate (a sliding 60-second window per client IP and model, with the limit computed as 60 s x slots x share / EWMA(service seconds) and clamped; cold-load requests are excluded from the average), and fit (if the model is not resident and cannot fit beside what is loaded, a 507 that names the resident model and the swap commands). Measured service times and an event log persist in SQLite so limits survive a restart. All coupling to oMLX internals is isolated in one function in pool.py, which reads the engine pool status; launch.py attaches the middleware to oMLX's app and hands the command line to oMLX's own CLI unchanged, so oMLX stays a pinned, unmodified dependency instead of a fork.
Features
- Size classification from the model id (the largest <n>B wins, so an MoE model is bounded by total parameters, not active ones)
- Global concurrency cap for big models
- Adaptive per-IP, per-model requests-per-minute from an EWMA of measured request time, with floor, ceiling and fallback before samples exist
- Memory fit pre-check with a readable 507 instead of a kernel-level error
- Swap thrash guard: model unloads always allowed, loads capped per minute
- Feedback headers (x-ratelimit-*, measured average and last request seconds, suggested interval) and Retry-After on every 429
- GET /usage and /v1/usage self-describing contract
- Startup tripwires that log an error on a loopback bind or a second oMLX server process
- Configuration entirely by OMLX_GATE_* environment variables
How it was built
One Apple Silicon Mac serves local models to several clients, and when many asked for big models at once, requests timed out or forced model swaps that cost 6 to 16 seconds each.
The gate was first written as a patch inside a fork of oMLX with 29 tests. The fork fell 168 commits behind upstream, so every upstream improvement meant a rebase.
On 2026-08-22 it was extracted as ASGI middleware attached at launch, so an oMLX upgrade became a tag bump. Everything that reads oMLX internals lives in one function that degrades instead of taking the server down.
Rate limits come from measured service time per model. Cold loads were excluded after one 66-second sample produced a limit about 25 times too strict for a model that answers in about 2.7 seconds.
AI coding agents did the extraction, and Rico decided to stop maintaining the fork and keep oMLX's own command line intact.