RodaddyBench
Free for noncommercial use under PolyForm Noncommercial 1.0.0; commercial use needs a licence from Rico. View the source
- Runs a set of JSON test cases against every model exposed by an OpenAI-compatible LiteLLM proxy. - Scores each answer deterministically where there is a right answer (exact match, regex, command validation, structured output, weighted checklists) and with an LLM judge where quality is subjective. - Stores every run (JSON files and SQLite), compares runs, flags regressions, and charts per-model trends over time. - Compares cached and non-cached variants of the same model. - Shows results in a terminal report, a single-file HTML viewer (viewer.html) and a Next.js dashboard (dashboard/).
Experimental
The problem
Public leaderboards test generic tasks. They do not say which model writes the best code review for my TypeScript, gives the correct Proxmox command, or drafts a post in a usable tone. Model updates also change behaviour without notice. A small benchmark built from real task types, re-run whenever a model changes, answers that directly.
How it works
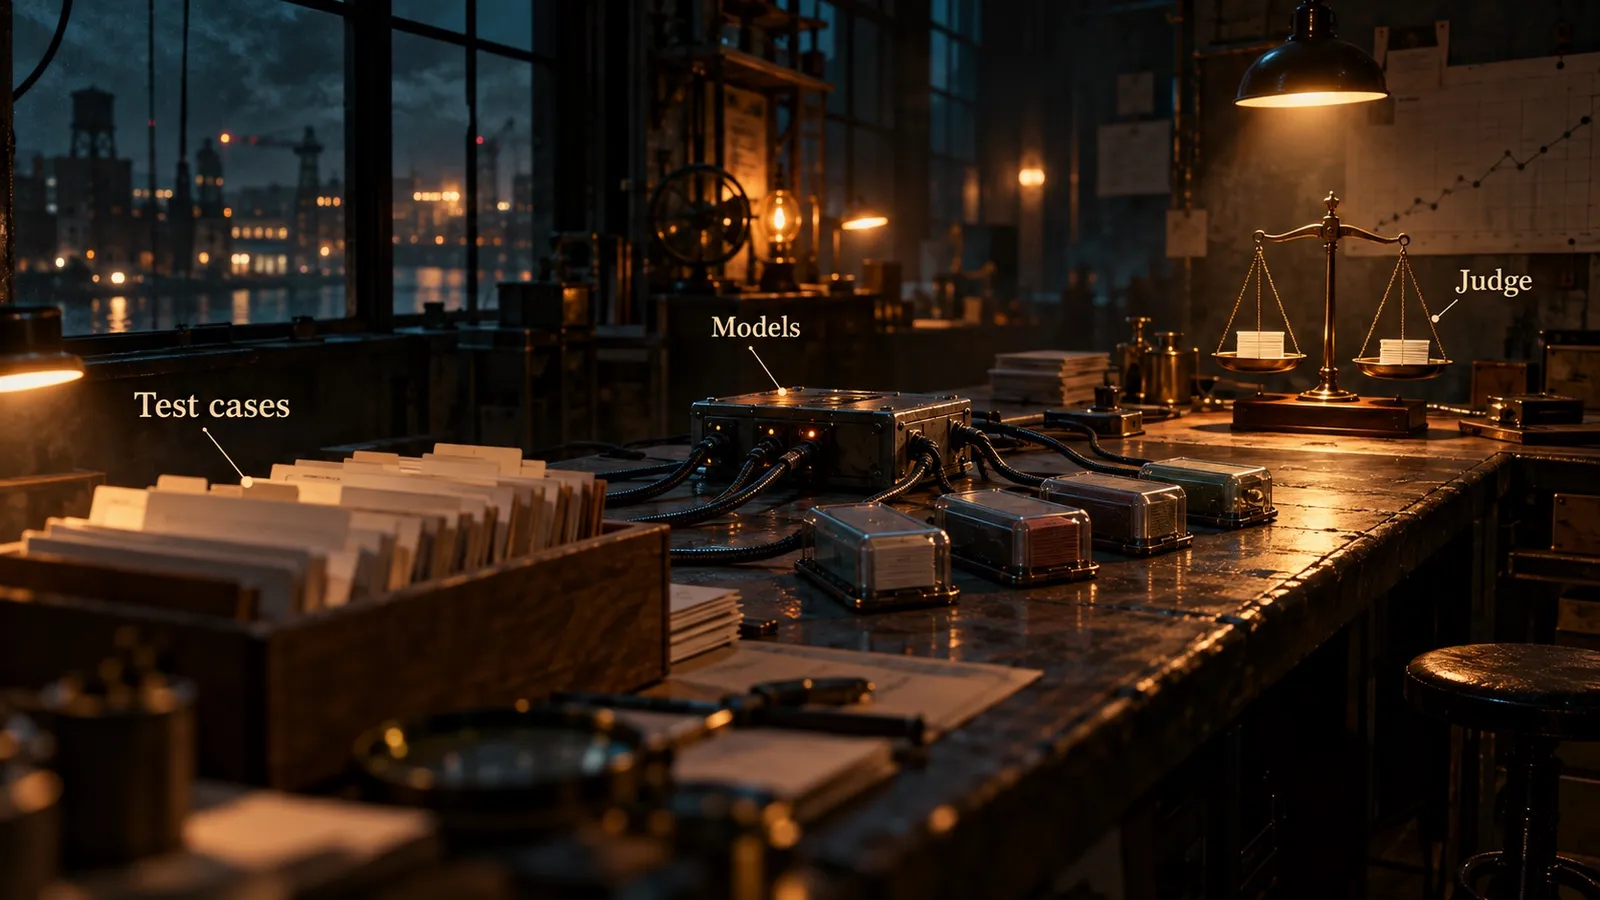
The CLI loads and validates test cases with Zod, fans them out to every model through the LiteLLM proxy (OpenAI SDK), and scores each response with the method the test case declares. Judge scoring picks a judge from a different vendor family than the model under test (Claude does not judge Claude), scores against a weighted per-category rubric, and runs a position-swapped second pass to detect position bias. Each test case is content-hashed so history stays comparable when a case changes. Each run is written to results/runs/ as JSON and to SQLite, which the dashboard reads.
Features
- bench run | compare | history | trends | cache-compare | migrate
- Six scoring methods behind one discriminated-union test-case schema
- Cross-vendor judge selection and position-swap bias check
- Regression detection between runs with a configurable threshold
- Terminal tables, sparklines and trend charts
- 21 test cases today across three categories: code review, content generation, infrastructure commands
How it was built
rodaddybench started on 2026-02-23, with 119 commits in the first two days, because public leaderboards did not predict which model did best on the real daily work: TypeScript review, Linux commands and technical writing.
Scoring is deterministic wherever a right answer exists. Commands and structured output are checked by code, and an LLM judge is used only for subjective quality, with partial credit instead of pass or fail.
A model never judges its own family. A later phase existed because proxy aliases had been hiding the real vendor and breaking that rule.
Known judge biases are controlled with position swapping and a conciseness criterion, and every test case is content-hashed so a changed case is never mistaken for a model regression.
Claude Opus wrote the code through a plan, execute and verify workflow, with a QA agent running acceptance checks. Rico chose the tasks and the questions the benchmark answers.